Meet TuringData at Asia’s Premier AI Event — SuperAI 2026
10–11 June 2026 | Marina Bay Sands, Singapore
AI-Native Storage Powering the Agentic AI Era
As AI shifts from static models to agentic, inference-driven systems, the real bottleneck is no longer compute — it is data movement at scale. In the emerging Token Factory era, AI systems continuously generate and reason over massive data streams, demanding high-throughput, low-latency, GPU-efficient infrastructure.
TuringData powers a full-stack data platform for training, inference, RAG, and agentic workloads, enabling higher GPU utilization and scalable AI systems for production environments.
The Storage Layer Agentic AI Demands
Agentic AI needs continuous, high-throughput data delivery at every inference step — not just at training time. TuringData keeps every GPU fully fed, at any scale, without bottlenecks.
From Token Factory to Competitive Edge
Token efficiency is the new unit of AI economics. TuringData delivers 91% reduction in TTFT and 8× increase in token throughput — turning your GPU investment into measurable ROI.
Start Pragmatic. Scale Without Limits
Deploy from 3 nodes. Scale to exabytes. No re-architecture required. TuringData runs on bare metal, on-premises, and any cloud — growing with your AI ambitions from day one.
TuringData Speaking Session
The Infrastructure Behind Agentic AI: Storage, Speed, and the Economics of Inference at Scale
Agentic AI is no longer a prototype — it is in production. And it is exposing an infrastructure gap that more GPUs alone cannot fix. As AI systems scale from single-model inference to multi-agent workflows, KV Cache grows unbounded, latency windows shrink, and storage becomes the constraint no one planned for.
In this session, Nikhil Madan explores why storage architecture — not compute capacity — has become the defining constraint of production-grade agentic AI, and what a purpose-built infrastructure stack looks like for enterprises ready to move beyond the prototype stage.
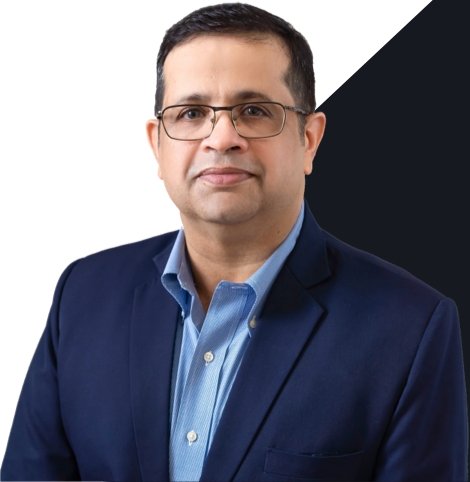
Nikhil Madan
Vice President, International Sales & Market Expansion
- Wednesday, 10 June
- 10:30-10:55
- The Forum Stage, Level 5, Marina Bay Sands, Singapore
Catch Our Booth Sessions:Deep Dives into Next-Gen
AI Infrastructure
We will host an exclusive series of technical talks right at our booth (PB16). Each 30-minute session dives deep into the infrastructure challenges shaping modern AI Factories — from full-stack storage architecture to inference acceleration and megacluster networking.
Reserve your spot in advance, show up at the booth on time, and walk away with an exclusive TuringData gift — only available to session attendees. Seats are limited. Secure yours now.
Agenda
- 10 June·3:00 - 3:30 PMFrom Training to Inference: The Full-Stack Storage Infrastructure Your AI Factory Needs
- 11 June·11:00 - 11:30 AMThe New AI Token Economics: Making More Tokens without Buying More GPUs
- 11 June·3:00 - 3:30 PM
Smashing the Megacluster Network Congestion: Fully Utilizing Every Bit of Your BandwidthBridging the Object-File Divide: Unlocking Legacy Data for Instant AI Innovation
Reserve Your Seat
Fill in your details below to secure your spot. Our team will confirm your booking shortly.
Select Session (Required)
Book A 1:1 Meeting with Our Experts
See AI-Native Storage with Lean Architecture and Extreme Performance in Action
Stop by the TuringData booth to meet our team, explore live interactive demos, and see next-gen AI data infrastructure in action. Whether you're building an AI factory, scaling inference workloads, or planning your sovereign AI infrastructure — we're here to help you find the right data foundation.
Want to go deeper? Skip the exhibition noise and take the discussion further. Book a 1:1 meeting with our principal architects today to get a tailored blueprint for your unique project workloads.
 Booth:PB16
 Date:10-11 June 2026
 Location:Marina Bay Sands, Singapore
Secure Your Meeting Slot!
Preferred Meeting Day (Required)
Download AI Infrastructure Resources
Explore technical papers, solution briefs, and product materials from TuringData AI Storage Platform.
Download AI Infrastructure Resources
Explore technical papers, solution briefs, and product materials from TuringData AI Storage Platform.
TuringData Accelerates the Demanding Data-Intensive Workloads
TuringData’s ultra-fast storage, built for high throughput, low latency, and seamless scalability, delivers faster results for your AI and HPC applications.
TuringData Cache Fabric Turns Your AI Factory into a Powerful Token Machine
Extend GPU memory to near-unlimited capacity and dramatically boost token throughput and GPU utilization, reshaping the economics of AI inference workloads.
TuringData Flash F9100/F9200: Unlock the Full Potential of Your GPUs
TuringData all-flash appliances feed GPUs with continuous, high-speed data streams, unlocking full computing power for faster AI training and real-time inference.
TuringData Platform Powers Your AI Initiatives at the Speed of Thought
A high-performance storage platform that delivers the speed, scalability, and efficiency required for modern AI workloads.
Leading CSPs Leverage TuringData for GPU Optimization
TuringData delivers AI-native high-performance storage that maximizes GPU utilization, accelerates AI workloads, and scales seamlessly across multi-tenant environments.
Boost Token Efficiency with TuringData AI Memory Solution
TuringData utilizes all available storage resources and provides PB-scale persistent storage for KVCache, allowing users to enjoy real-time inference at minimal cost.
Streamlining Data for Rapid GenAI Results
TuringData provides the fastest, most scalable storage for Generative AI, delivering the performance developers expect and enabling your team to focus on building innovative GenAI projects.
Supercharge the World's Largest AI Workloads
TuringData delivers consistent, lightning-fast access to data at scale across the entire AI workflow, supporting the training of larger AI models and driving cutting-edge AI innovation.
Find out how much GPU utilization you're leaving on the table. Schedule a free 30-minute architecture review with our experts.